 HopBase
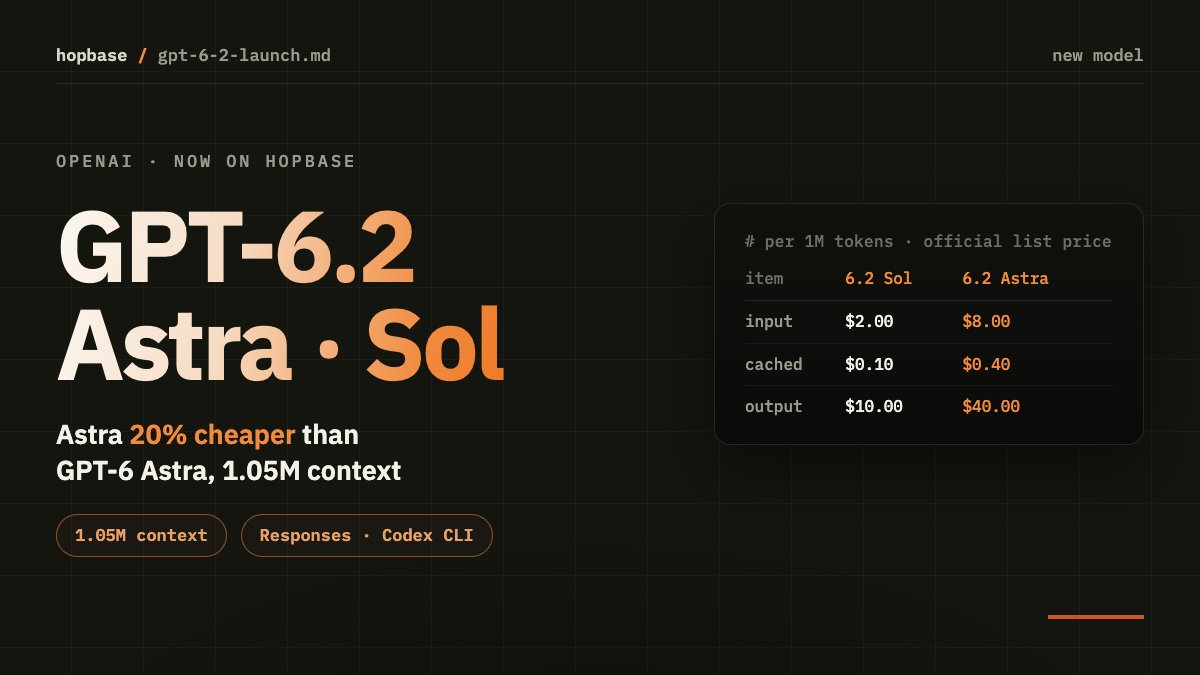
GPT-6.2 Astra (gpt-6.2-astra) and GPT-6.2 Sol (gpt-6.2-sol), released by OpenAI on 2026-11-17, are live on HopBase in the Codex Plus and Codex Pro groups. Both work over the OpenAI-compatible POST /v1/responses and POST /v1/chat/completions endpoints, and Codex CLI and the Codex app can use them directly. Each has a 1.05M-token context window and up to 128K output tokens. Billing follows OpenAI's official list price: GPT-6.2 Sol costs $2 input, $0.10 cached input and $10 output per million tokens; GPT-6.2 Astra costs $8 input, $0.40 cached input and $40 output, which is 20% cheaper than GPT-6 Astra ($10 / $1 / $50) on input and output and 60% cheaper on cache reads. Once a single request's input exceeds 272K tokens, input and cached input bill at 2x and output at 1.5x.
Updated 2026-11-19: prices checked against OpenAI's official pricing page; endpoints and specs verified on the HopBase production gateway.
Up and running in three minutes: sign up for the HopBase console, create a key, add the Codex Plus or Codex Pro group to it, set the Base URL to https://api.hop-base.com/v1 and the model to gpt-6.2-sol or gpt-6.2-astra.
Astra or Sol: which one to use
- GPT-6.2 Sol is the workhorse for everyday coding, agents and tool calling. It costs the same as GPT-6.1 Sol ($2 / $10), and its $0.10 cache read is half of GPT-6 Sol's $0.20, which adds up in long agent sessions that resend the same context.
- GPT-6.2 Astra is the flagship tier for hard reasoning and code review, where getting it right the first time matters. It costs 4x Sol per token but 20% less than the previous flagship, GPT-6 Astra.
- A practical split: build the workflow on Sol, and route only the review and hard-debugging steps to Astra.
Pricing (official list price, per 1M tokens)
| Item | GPT-6.2 Sol | GPT-6.2 Astra | GPT-6 Astra (for comparison) |
|---|---|---|---|
| Input | $2 | $8 | $10 |
| Cached input | $0.10 | $0.40 | $1 |
| Output | $10 | $40 | $50 |
| Input above 272K | Input and cached input ×2, output ×1.5 (whole request) | ||
You are billed at list price × actual usage; the effective rate depends on your group. See the pricing page.
How to call it
- Base URL:
https://api.hop-base.com/v1with Bearer authentication. With the OpenAI SDK, change only the Base URL and API key. - Endpoints:
POST /v1/responses(recommended, and the default for Codex tools) andPOST /v1/chat/completions. - Groups: available in Codex Plus and Codex Pro. The GPT Official Direct (Azure) group does not serve GPT-6.2 yet.
- Reasoning effort:
reasoning_effort(reasoning.efforton Responses) ran in production on launch day at high, xhigh and max.
curl https://api.hop-base.com/v1/responses \
  -H "Authorization: Bearer sk-your-key" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6.2-sol",
    "input": "Explain idempotency in three sentences",
    "stream": true
  }'
from openai import OpenAI
client = OpenAI(base_url="https://api.hop-base.com/v1", api_key="sk-your-key")
resp = client.chat.completions.create(
model="gpt-6.2-astra",
messages=[{"role": "user", "content": "Review this code for concurrency bugs: ..."}],
)
print(resp.choices[0].message.content)Codex CLI and the Codex app
~/.codex/config.toml:
model_provider = "hopbase"
model = "gpt-6.2-sol"
model_reasoning_effort = "high"

[model_providers.hopbase]
name = "HopBase"
base_url = "https://api.hop-base.com/v1"
wire_api = "responses"
requires_openai_auth = true
Put {"OPENAI_API_KEY": "sk-your-key"} in ~/.codex/auth.json. Full steps are in the Codex CLI guide.
What we saw on launch day
- Stream your requests. Both models reason before they answer, so at high reasoning effort the first token often takes ten seconds or more. For non-streaming calls, set your client timeout to at least 300 seconds.
- Long context works. Production requests with more than 300K input tokens completed successfully; the part above 272K bills at the long-context rate shown above.
- Caching is automatic. Multi-turn requests that share a prefix hit the cache and bill at $0.10 (Sol) or $0.40 (Astra) per million cached tokens, a large saving for agents.
Full specs: GPT-6.2 Sol model docs and GPT-6.2 Astra model docs.
FAQ
How much does the GPT-6.2 API cost?
At OpenAI list price, GPT-6.2 Sol is $2 input, $0.10 cached input and $10 output per million tokens; GPT-6.2 Astra is $8, $0.40 and $40. When a request's input exceeds 272K tokens, input bills at 2x and output at 1.5x.
How is GPT-6.2 different from GPT-6.1?
GPT-6.2 Sol has the same list price as GPT-6.1 Sol. GPT-6.2 adds a flagship Astra tier priced 20% below GPT-6 Astra. Both generations have a 1.05M context window and up to 128K output tokens.
Can I use GPT-6.2 in Codex CLI?
Yes. In config.toml, point the provider at https://api.hop-base.com/v1 with wire_api = "responses" and set the model to gpt-6.2-sol or gpt-6.2-astra. Your key must include the Codex Plus or Codex Pro group.
What does 404 model_not_found mean?
The groups on your key do not include the model. Add Codex Plus or Codex Pro to the key in the console, then confirm with GET /v1/models.